Como estava esse conteúdo?
Idioma do conteúdo
No momento, nem todo o conteúdo está traduzido.
- Aprenda
- In vivo from the first design: how Manifold Bio scaled protein design across AWS Regions
In vivo from the first design: how Manifold Bio scaled protein design across AWS Regions
Manifold Bio is an AI protein design and data generation company that uses molecular barcoding technology to test biologic drug candidates directly in living systems. Find out how Manifold scaled its protein design capacity across AWS Regions with the Global Capacity Orchestrator and its internal scheduler, Regatta.

Most biologic drug candidates are designed and optimized in a dish, with most of them failing once they reach a living system. A molecule that binds beautifully on a plate can distribute to the wrong tissue, clear too fast, or never cross the barrier it needs to cross. The information that determines whether a drug works, including pharmacokinetics, biodistribution, and tissue specificity, exists only in vivo. Traditionally, researchers could only measure those properties for one candidate at a time.
Manifold Bio, an AI protein design and data generation company in Boston, was built around closing that gap. Rather than screening in vitro and hoping the results transfer, Manifold measures candidate molecules directly in living systems, at a scale that was previously impossible.
The enabling invention is a molecular tracking technology called mCodes: inert peptide barcodes attached to each therapeutic molecule and read using high-affinity detectors and DNA sequencing. Because every candidate carries its own barcode, Manifold can quantify hundreds of molecules across multiple tissues in a single animal and recover the properties that predict whether a candidate could become a drug: where it went, how long it stayed, and what it reached. That measurement engine feeds an AI design engine, and the two operate as a loop: design, build, test in vivo, learn, and design again.
That loop is producing notable results. In November 2025, Manifold announced a strategic research collaboration and license agreement with Roche to develop brain-targeted medicines for neurological and neurodegenerative diseases. The agreement included $55 million USD upfront and the potential for more than $2 billion USD in research, preclinical, clinical development, and commercial milestones, plus tiered royalties. In March 2026, Manifold announced a joint study with NVIDIA evaluating Proteina-Complexa, NVIDIA's generative model for protein binder design. With the NVIDIA team, Manifold co-designed and tested one million binder designs against 127 targets in a single multiplexed experiment, measuring more than 100 million protein-protein interactions.
A million designs in one experiment is a different kind of science, and it moves the bottleneck out of experimental validation and onto the GPUs. This article explores how Manifold overcame that second bottleneck internally: with the Global Capacity Orchestrator, an AWS open-source project that makes accelerator capacity across AWS Regions available through a central API, and Regatta, the scheduler Manifold's engineers built on top of that API.
When design becomes the rate-limiting step
In the history of drug discovery, the wet lab has been the constraining factor. Manifold inverted that relationship. Once experimental validation can keep pace with a million protein designs, the question becomes whether the team can generate, fold, score, and rank designs fast enough to keep the experiments fed.
Manifold's design stack includes mBER, its protein design framework for epitope-specific antibodies. In September 2025, Manifold released mBER as open source after using it to design and test more than 1.1 million VHH antibodies against 145 targets. The framework has since been used beyond Manifold. In a collaboration between Memorial Sloan Kettering Cancer Center and the Amazon Bio Discovery team, mBER was one of three design methods used to generate 288,000 nanobody candidates against a novel cancer target, with the top 100,000 advanced to wet-lab screening. The resulting study reported nanomolar to sub-nanomolar binders.
Manifold has since developed mBER-2 and reports that its iterative design loop produced binders for 98 percent of targets in another million-scale campaign using the new framework. The team is now running mBER-2 on AWS with the goal of discovering binders to every addressable epitope across the human proteome. Running protein design at proteome scale creates a GPU orchestration challenge with three characteristics:
- Demand is inconsistent: Design campaigns are not a steady stream of inference. When a campaign begins, the team needs an enormous number of structures predicted as quickly as the science can absorb them.
- Capacity is regional and time-varying: Accelerated instances are not uniformly available across AWS Regions. A pipeline pinned to one Region is a pipeline that waits.
- The orchestration is expensive to build and maintain: Multi-Region scheduling, capacity-aware placement, Spot fallback, and scaling to zero between campaigns require a platform engineering investment that Manifold would rather put toward the science.
Erik Swanson, AI/ML Team Lead at Manifold says: "We are a team of scientists working to feed a drug discovery engine of enormous scale. We needed a clean engineering solution that could enable tens of millions of protein designs in a week. We knew this would require a custom compute-scaling platform, but we did not want to build a company around it, so we turned to our team at AWS."
The requirement was specific, and extended beyond just GPUs. Manifold wanted its scientists, and increasingly, agents acting on their behalf, to submit design jobs that could land wherever accelerators were available without requiring the company to build and staff a multi-Region orchestration platform.
Manifold and AWS were already working together. Manifold was one of 40 startups selected globally for the 2025 AWS Generative AI Accelerator. In 2026, the team brought its inference-scaling challenge to the AWS Custom Model Inference Fellowship, a structured engagement with defined milestones and hands-on architecture support for startups operating their own models in production. The goal was not a proof of concept. It was production infrastructure that Manifold could operate itself.
The Global Capacity Orchestrator: one central API across Regions
The starting point was the Global Capacity Orchestrator (GCO), now published as official AWS guidance and available as open source under MIT-0. GCO deploys consistent Amazon EKS Auto Mode clusters across selected AWS Regions and puts a central API in front of them. Concretely, that provides:
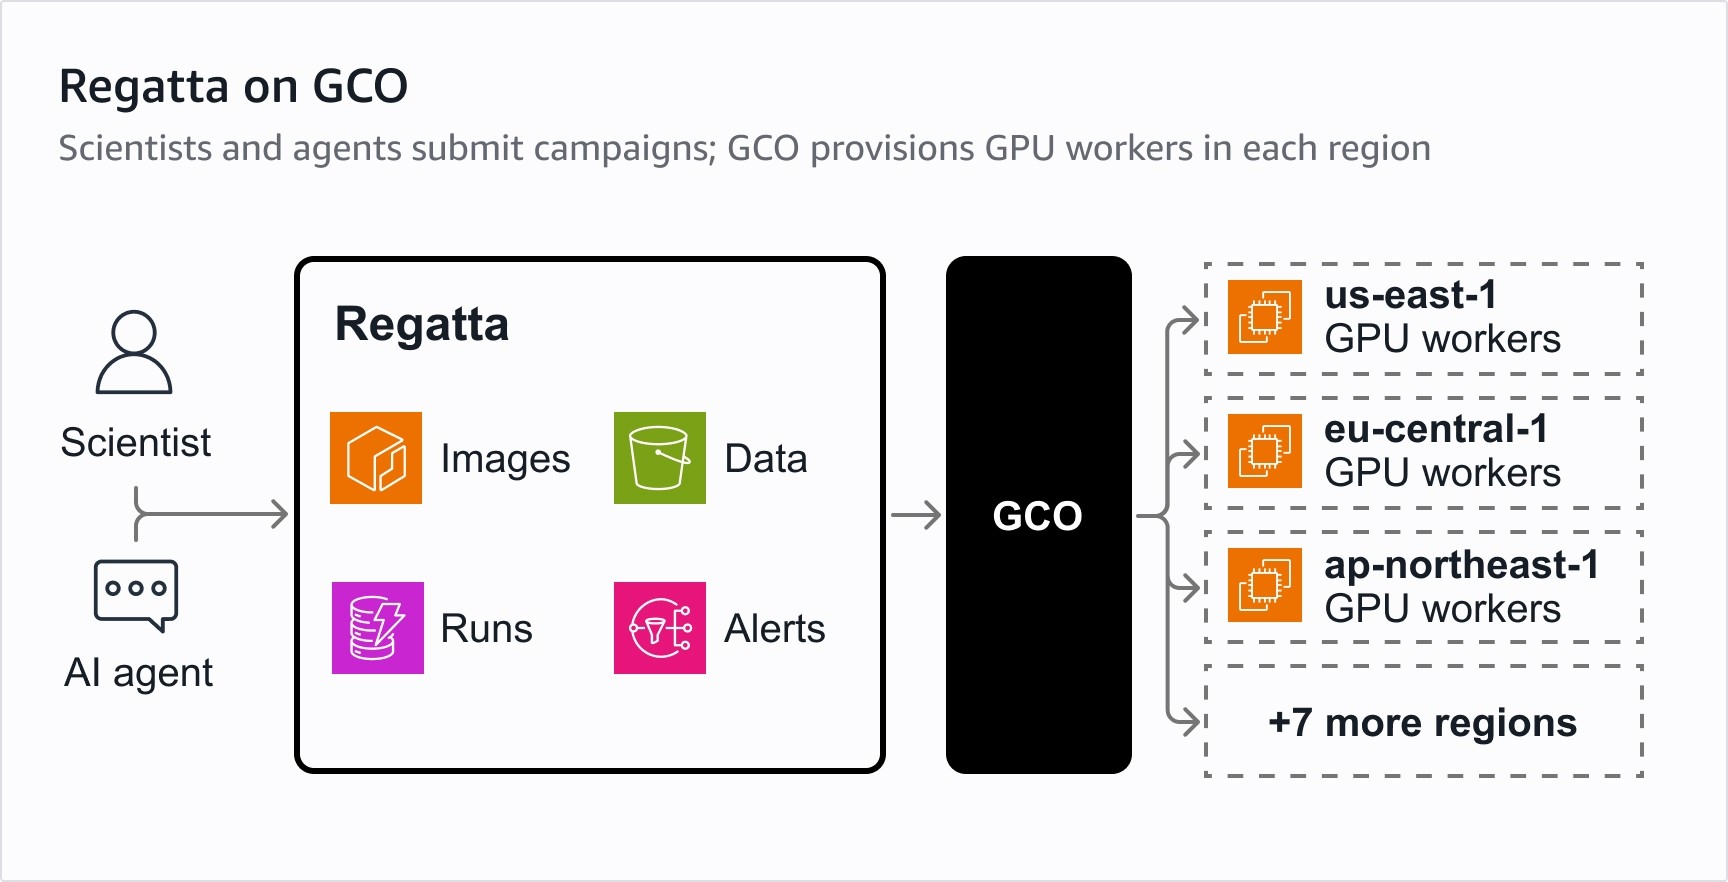
- One API without per-cluster credentials: Jobs are submitted as Kubernetes manifests through a REST API signed with AWS Identity and Access Management (IAM) Signature Version 4. Users do not need kubeconfig files or per-Region setup.
- Capacity-aware placement: GCO's placement workflows choose a target Region before scheduling based on available accelerator capacity and configured purchase options, including Spot capacity. Latency routing through AWS Global Accelerator remains separate from capacity placement.
- Accelerators provisioned on demand: EKS Auto Mode can bring up GPU, AWS Trainium, AWS Inferentia, or CPU nodes when a workload needs them and scale them down when it does not, avoiding a pre-provisioned fleet sitting idle between campaigns.
The design decision that mattered most for Manifold is easy to overlook: GCO is an API first and a toolset second. Submitting work is a signed HTTP request carrying a Kubernetes manifest. Everything shipped alongside GCO, including the GCO CLI, job queue, and Model Context Protocol (MCP) server, is a client of that same API. There is no privileged path reserved for AWS-authored clients, and a team can extend the platform without forking it.
That design made it possible for Manifold to put its own abstraction in front of GCO.
Regatta: simple, scalable GCO orchestration for protein design
Built by its in-house engineers, Regatta is Manifold’s scheduler. It presents design runs in the vocabulary Manifold's scientists use, then sends the resulting work to GCO for placement and execution. A researcher, or an agent working under a researcher's direction, can submit work through Regatta without thinking about Regions, clusters, node pools, or Spot interruptions.
Regatta lets Manifold own the interface its scientists touch while GCO handles the capacity layer underneath it. The integration uses GCO's API rather than cluster-specific credentials or a private extension point, so Manifold does not need to patch GCO or maintain a fork as either system evolves.
That separation matters for other startups facing the same decision. Rather than focusing on platform adoption over the needs of its scientists, the company treated GCO as a substrate and built the domain-specific interface its team needed. The scientist-facing abstraction could remain Manifold's because the layer underneath it was an API rather than a fixed product surface.
The resulting system became GCO's first production deployment.
What changed
The production system changed the scale, economics, iteration speed, and operational accessibility of Manifold's design campaigns:
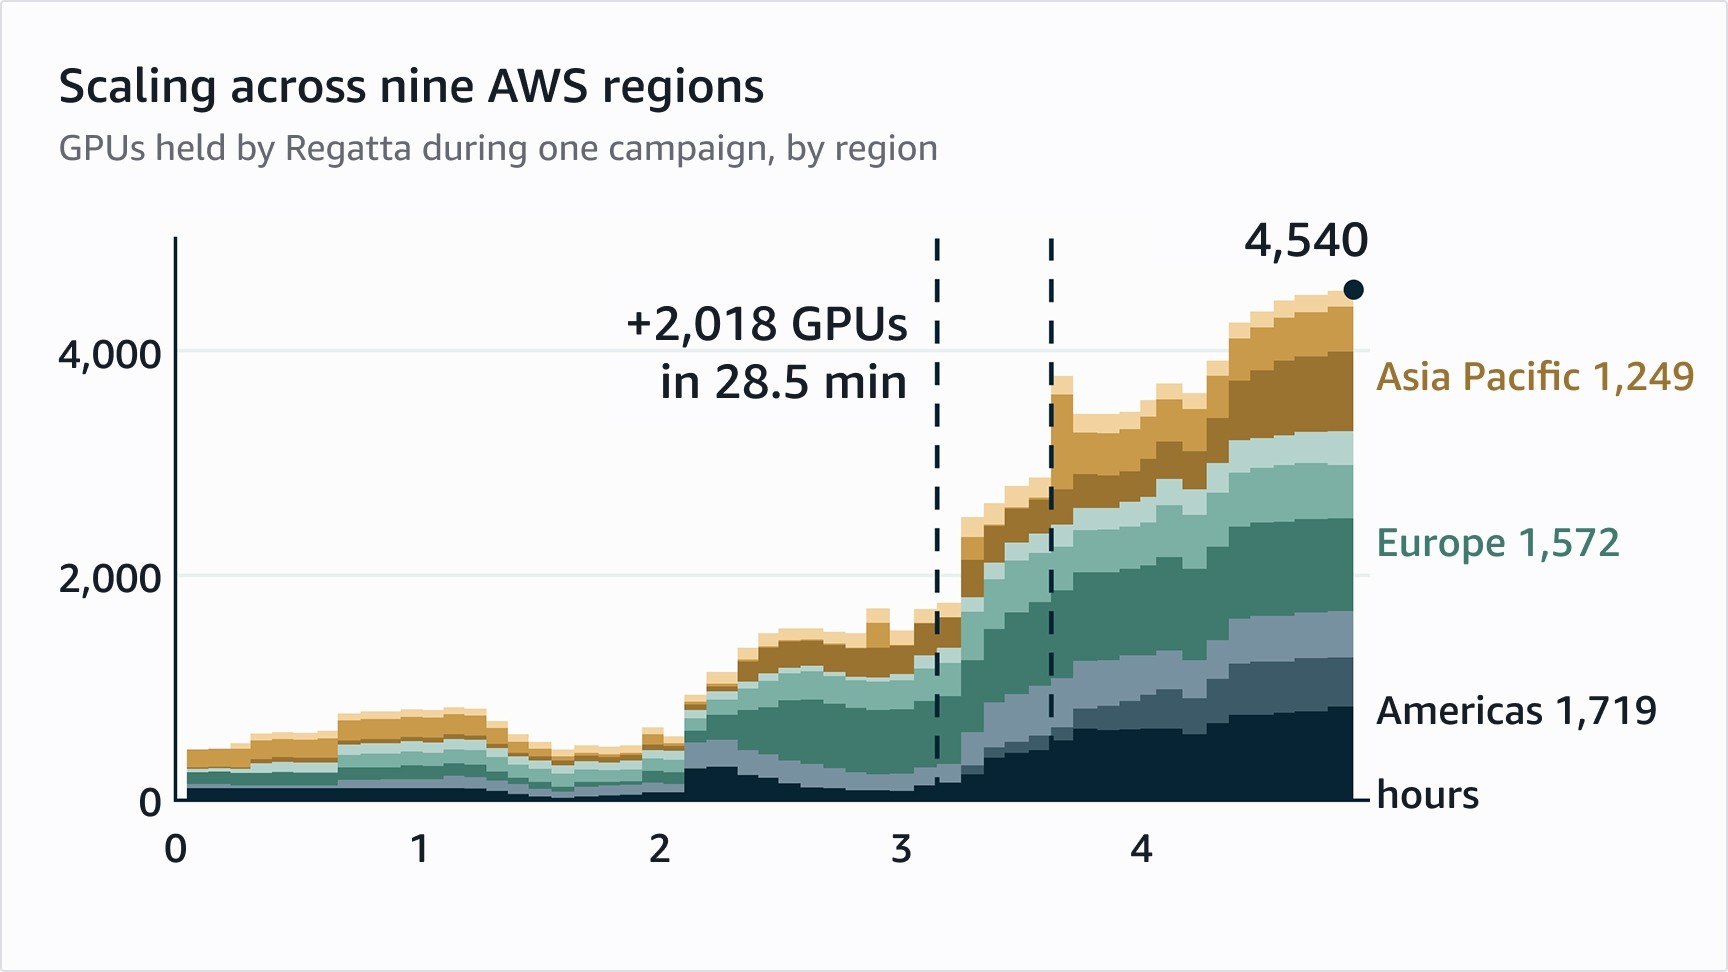
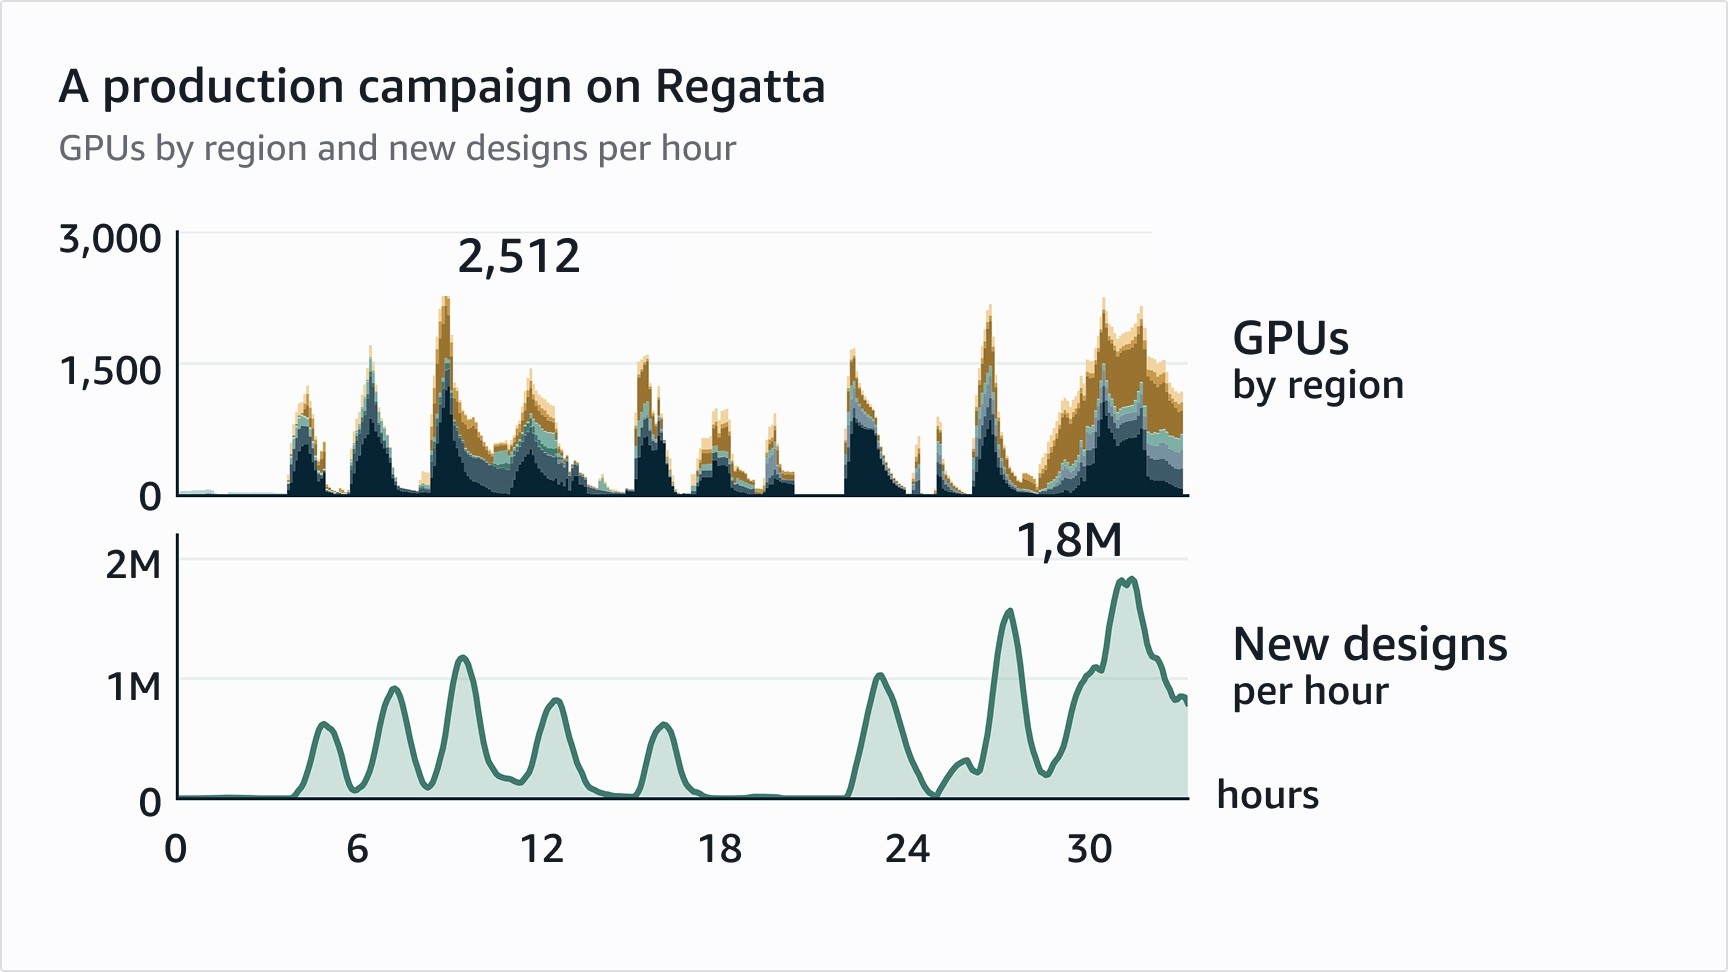
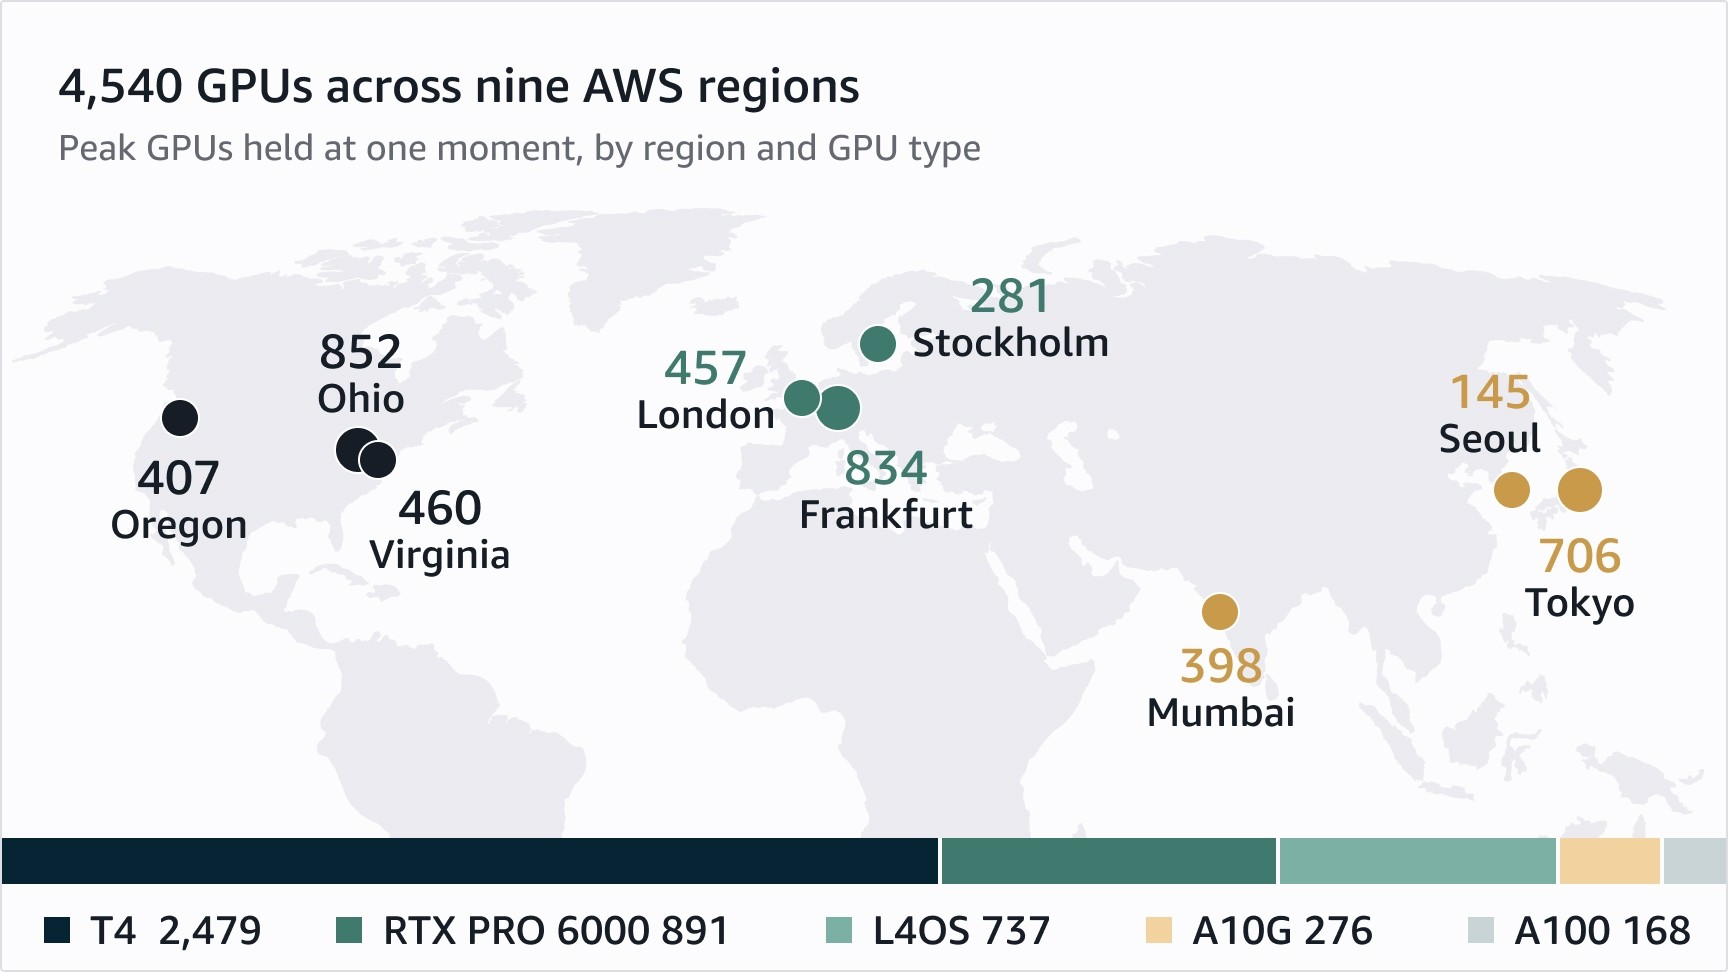
- 10 times the campaign scale: Before GCO and Regatta, Manifold could reliably use approximately 256 GPUs in a single Region for a campaign of roughly 10 million designs. The new system supports campaigns approaching 100 million designs by drawing on capacity across Regions, with greater access to Spot capacity and fewer capacity-related disruptions.
- 50 percent lower compute cost per designed binder: Price-aware use of Spot capacity across 10 AWS Regions cut Manifold's per-binder compute cost in half.
- Results in a week instead of a month: Design campaigns that previously took around a month can now be completed in about a week. Individual iteration cycles fell from approximately one week to two days, making it practical for scientists and engineers to test changes or launch smaller runs during a campaign.
- Multi-Region runs without a distributed-computing specialist: A single scientist or engineer, even with little experience in parallel computing, can configure and launch a multi-Region run using hundreds of GPUs in minutes. This now happens routinely. Manifold has also made the workflow increasingly agent-assisted: an operator can provide high-level requirements, and an agent can translate them into a run and launch it under the operator's direction.
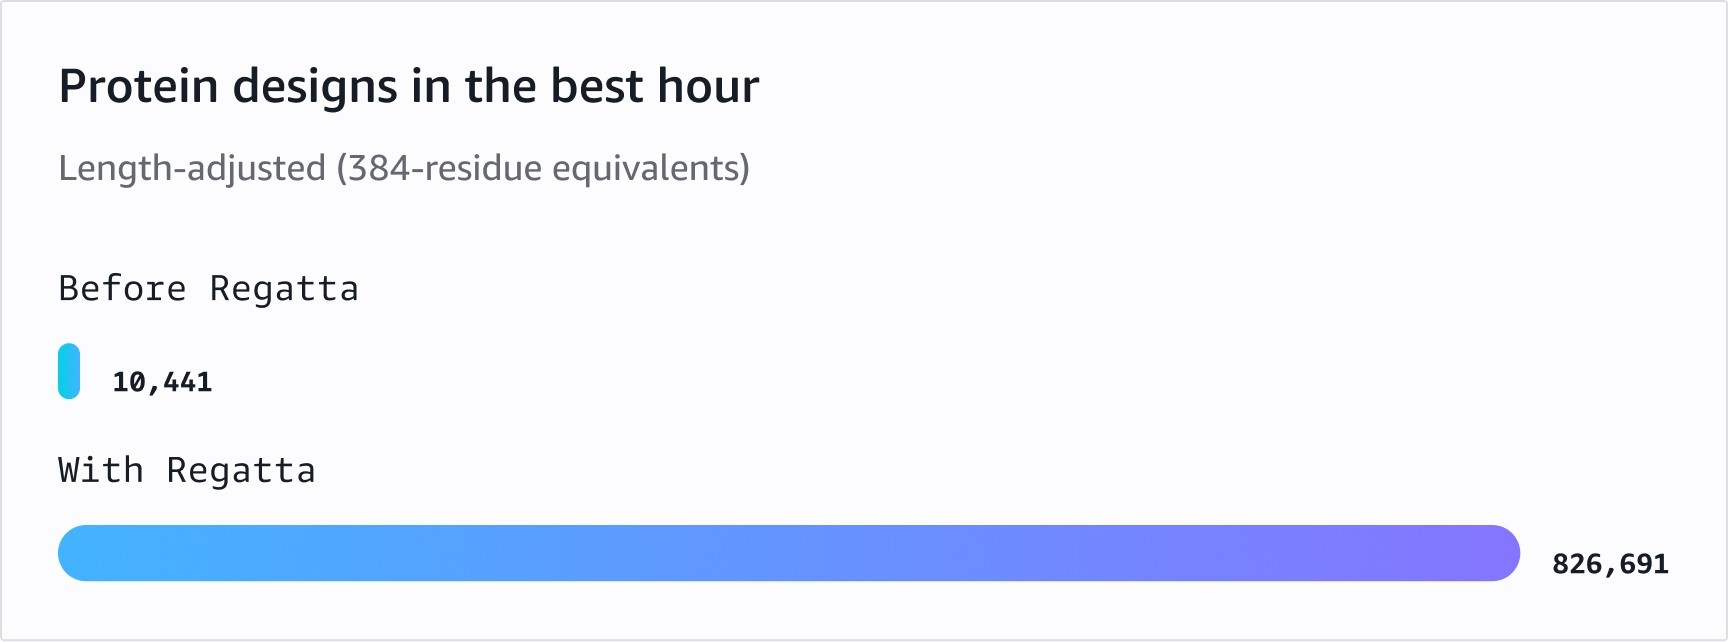
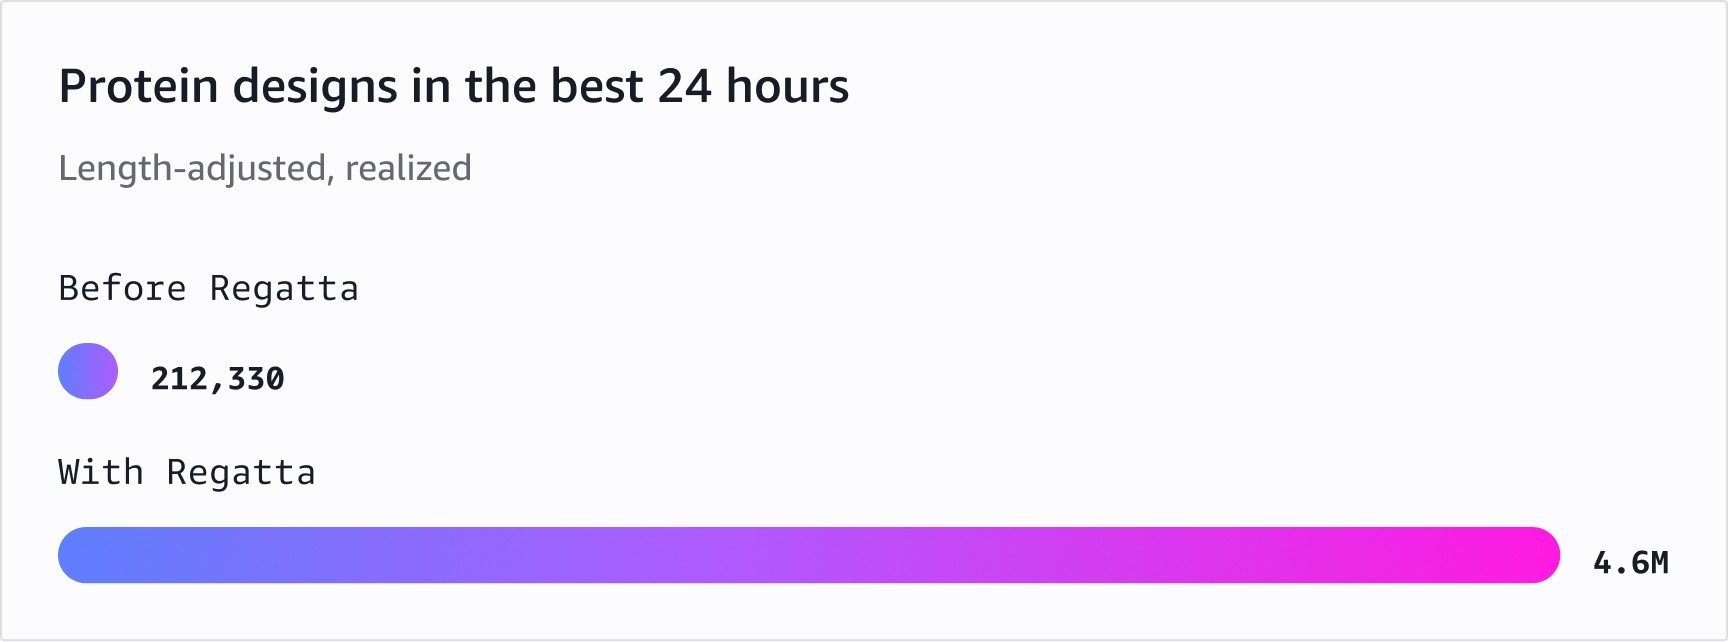
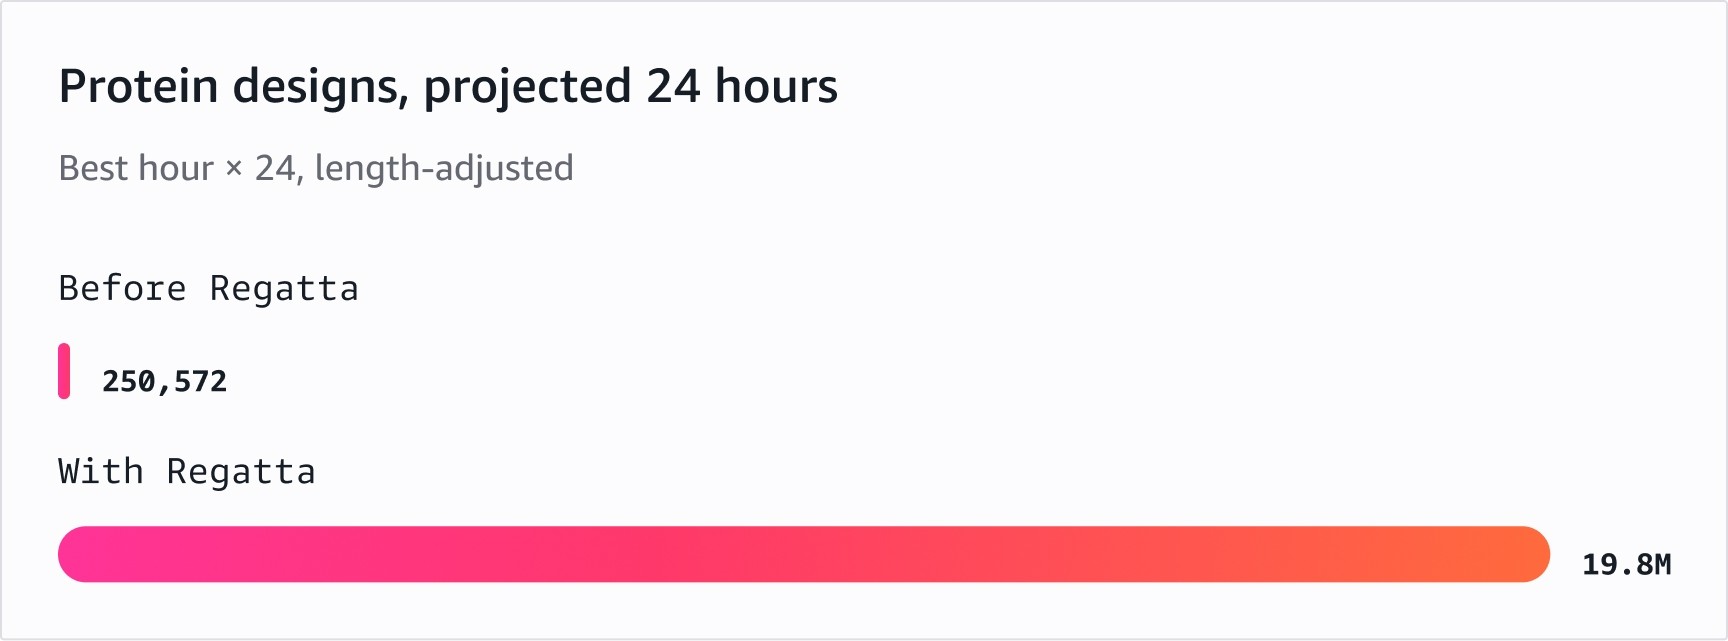
The fellowship concluded in July 2026 with the infrastructure in production and Manifold's team operating it.
What's next
Manifold is extending mBER-2 toward its goal of discovering binders to every addressable epitope across the human proteome. That direction will require larger campaigns, additional model architectures, and more agent-assisted runs, all behind the same Regatta interface. GCO gives the capacity layer room to expand without needing scientists to change how they launch and manage designs.
Try it yourself
Manifold's constraint was protein design, but the shape of the problem is not specific to biology. If you operate a model of your own, demand arrives inconsistently, and the accelerators you need are not reliably available in a single Region, you are looking at the same capacity problem. GCO provides a way to address it without building a multi-Region orchestration system from scratch.
GCO is open source under MIT-0, which permits commercial use without an attribution requirement:
- Guidance and implementation guide: Guidance for EKS AutoMode Clusters with Global Capacity Orchestrator on AWS
- Source: github.com/aws-solutions-library-samples/global-capacity-orchestrator-on-aws
- Manifold Bio: manifold.bio
- Open-source mBER: github.com/manifoldbio/mber-open
The reusable idea is the division of labor. Let the capacity layer expose a stable API that knows where accelerators are available, then spend domain engineering on the interface scientists actually use. That split lets Manifold run protein design inference across AWS Regions without turning a team of scientists into a platform engineering organization.
The interesting result is not the number of GPUs. It is what Manifold's design loop can discover when it is no longer waiting for them.
Jake Mevorach
Jake Mevorach é arquiteto sênior de soluções de IA generativa na AWS, em Boston, na equipe Frontier AI, e criador do Global Capacity Orchestrator. Ele dedicou grande parte de sua carreira à construção de infraestruturas que permitem que cientistas e pesquisadores trabalhem em grande escala sem precisarem se tornar engenheiros de plataforma — desde a plataforma de bioinformática que desenvolveu e disponibilizou como código aberto na Ginkgo Bioworks até a liderança de colaborações com a NASA, a Faculdade de Medicina de Harvard, a Faculdade de Medicina de Stanford e a Universidade de Columbia durante sua passagem pela AWS. Ele também é apaixonado pela área da saúde; enquanto trabalhava na AWS, foi coautor de um artigo publicado na revista *Nature Communications* que analisou o uso do aprendizado federado com preservação da privacidade no diagnóstico e na segmentação de tumores cerebrais pediátricos, e dedica seu tempo livre, fora do trabalho, a contribuir para os dois principais softwares de código aberto de prontuários médicos (OpenEMR e OpenMRS).
Ernst Schmid
Ernst Schmid é engenheiro de machine learning aplicado na Manifold Bio, onde trabalha no aprimoramento de métodos de projeto de proteínas in silico para o desenvolvimento de novas terapêuticas. O Regatta surgiu inicialmente a partir de sua visão de criar uma plataforma centralizada, fácil de usar e altamente escalável para executar trabalhos de computação em GPU paralelizadas para as campanhas de projeto da Manifold. Fora do trabalho, ele gosta de explorar novos restaurantes na região de Boston.
Rob Scheidegger
Rob Scheidegger é engenheiro de pesquisa em machine learning na Manifold Bio, onde se dedica a melhorar a eficiência do machine learning e a habilitar fluxos de trabalho de computação agêntica. Ele desenvolveu grande parte da integração entre o Regatta e os harnesses agênticos da Manifold. Em seu tempo livre, Rob costuma ser encontrado pescando nas montanhas Adirondacks ou nos arredores de Boston.
Erik Swanson
Erik Swanson lidera a equipe de pesquisa em IA/ML da Manifold Bio, onde sua equipe desenvolve os modelos de machine learning e a infraestrutura de GPUs que sustentam a plataforma de design de proteínas de alto throughput da empresa. Ele liderou o desenvolvimento do mBER, o sistema de design de ligantes proteicos da Manifold, que opera em grande escala em milhares de GPUs na AWS. Antes de ingressar na Manifold, Erik estudou física e matemática em Harvard, onde publicou pesquisas sobre o entrelaçamento quântico em buracos negros.
Mike Nichols
Mike Nichols é cientista sênior na área de Design de Proteínas na Manifold Bio. Ele desenvolve e realiza a implantação de sistemas de descoberta de ligantes proteicos de novo que combinam machine learning com triagem experimental em grande escala para criar medicamentos direcionados a tecidos específicos. Fora do trabalho, Mike escreve ficção e joga videogame em excesso.
Como estava esse conteúdo?